A story that contains its own beginning
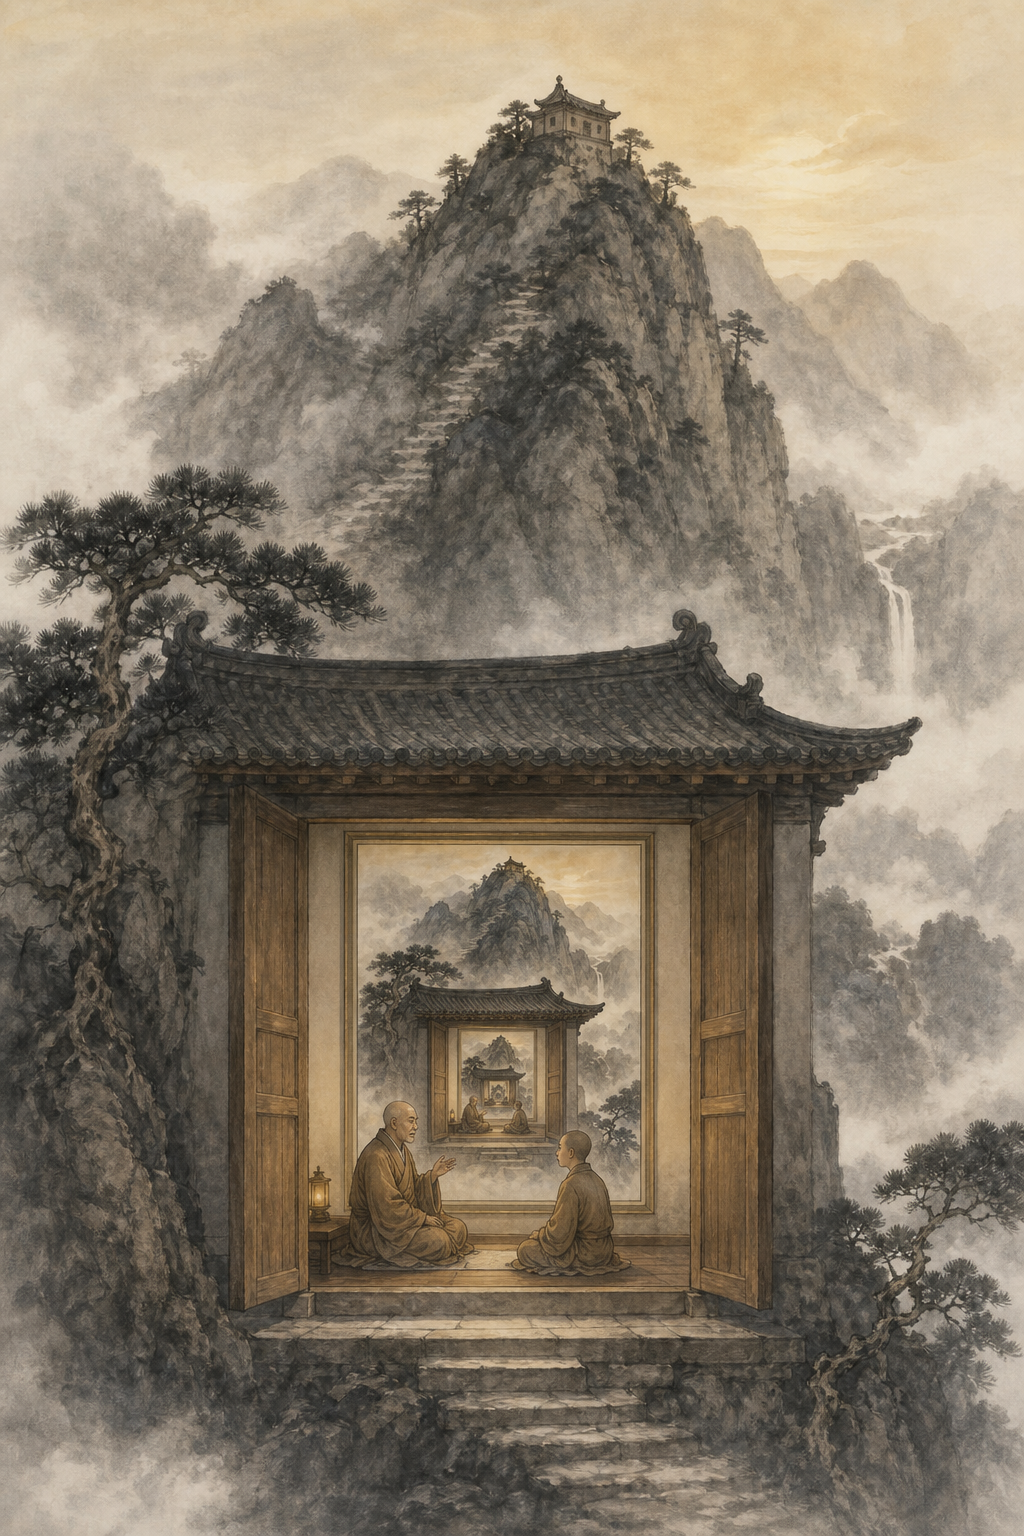
A monk tells a young monk a story. There is a mountain, a temple on that mountain, and a monk inside the temple telling a young monk a story. The story begins again. The location and the characters are familiar, but the interesting event happens in the act of telling: the inner story returns to the description that introduced it.
Now replace the temple with a painter. On the canvas is a room with a painter making a picture of that room. A reader who connects the two scenes has crossed a substantial gap. There is no shared monk, mountain, brush, or canvas. What survives is an organization: a representation reaches back toward the situation that contains it.
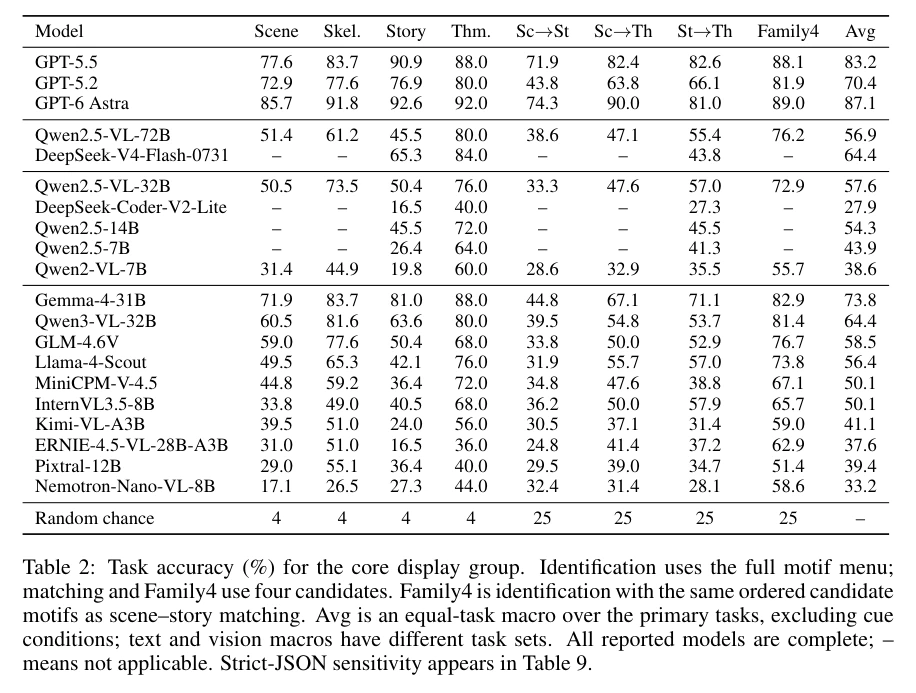
This is the starting point of GEB-Bench. We ask whether a model can recognize an abstract relation in one form and use it to find a corresponding relation in another. The benchmark makes the step from recognition to analogy visible by separating the component judgments from the final match.
From repetition to recursion and fixed points
The monk example gives an intuitive route into a family of mathematical ideas, but those ideas have different conditions. Repeating an event gives a cycle. Placing one object inside another gives nesting. A recursive construction applies a rule within its own subproblems. Self-reference points back to the statement or situation doing the referring. The task is to preserve the particular relation, including the detail that distinguishes these neighbors.
Write F for a rule that wraps a story inside a new story. Finite nesting produces F(x), F(F(x)), and so on. An indefinitely self-consistent unfolding can be described by the equation S = F(S). That is a fixed-point-style description of the unfolding. It does not make every nested picture a fixed-point theorem, nor imply that a finite photograph establishes an infinite object. It gives us a precise question to ask: what is repeated, what contains what, and where does the construction return?
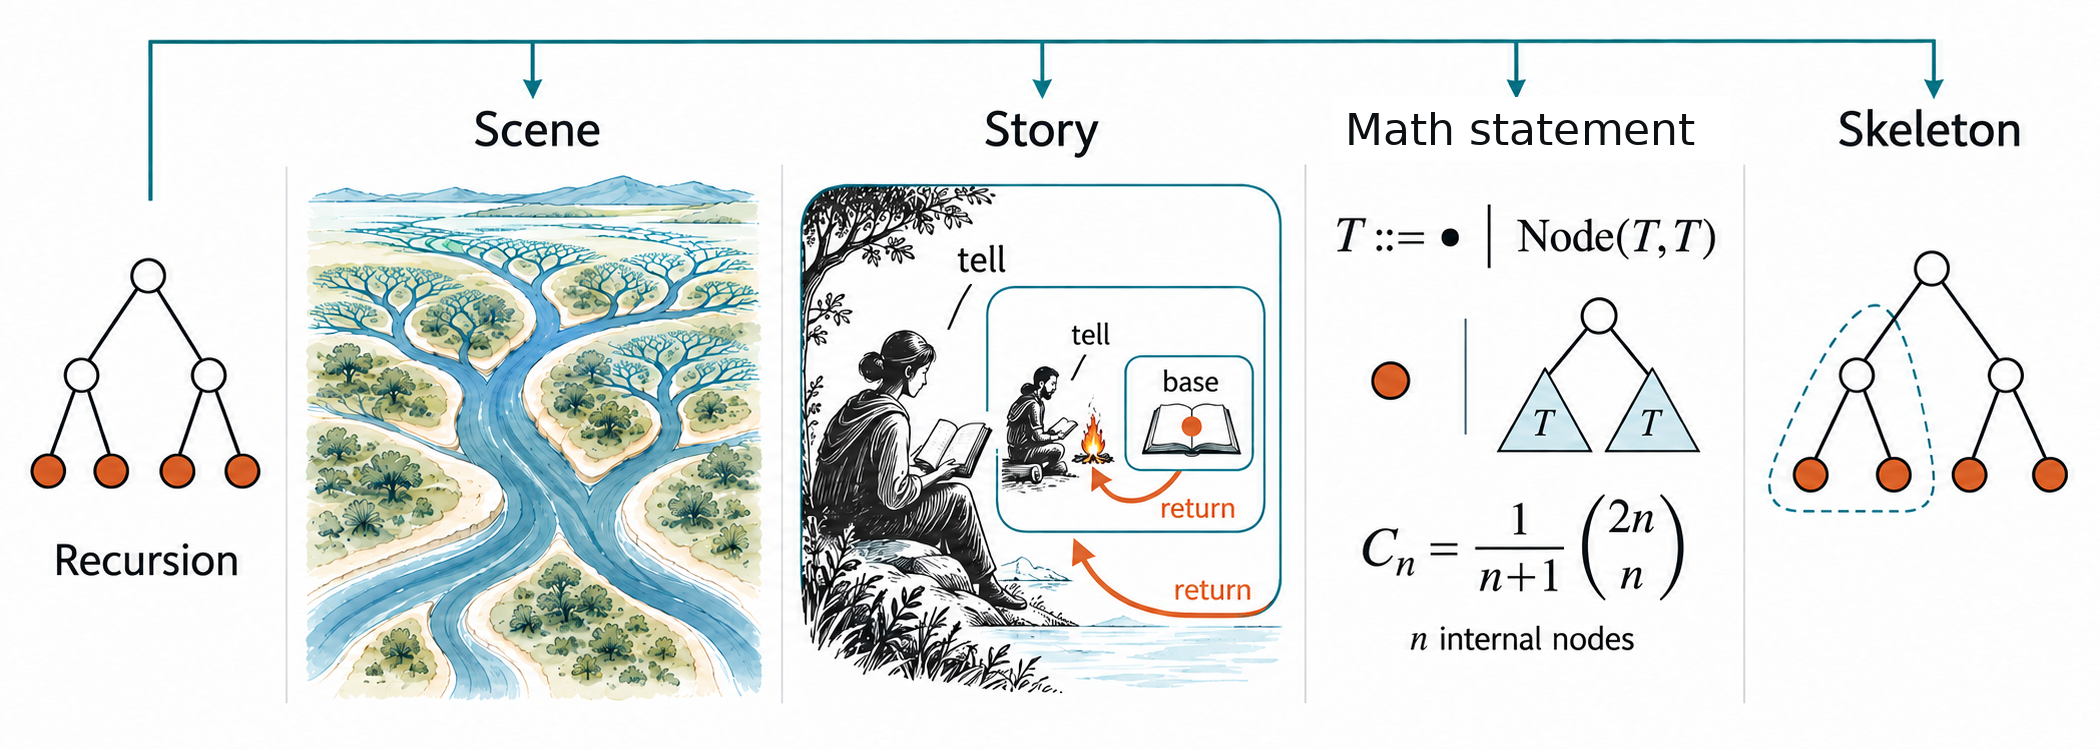
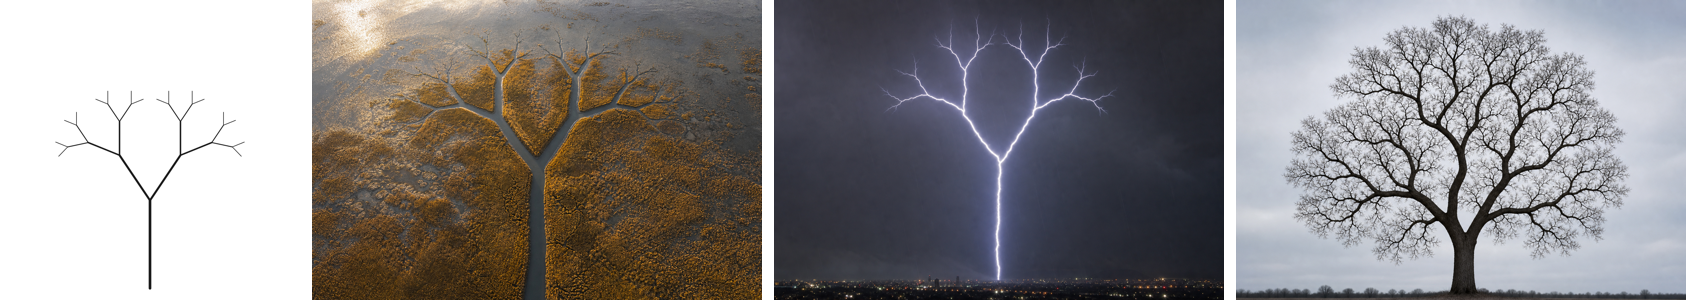
A river delta offers a different example. One channel branches into smaller channels, which branch again. Lightning and a recursively constructed tree can share that branching organization while differing in texture, scale, and physical origin. A loop that simply closes on itself lacks this repeated decomposition. The distinction is small in words and substantial in structure.
One relation, four voices
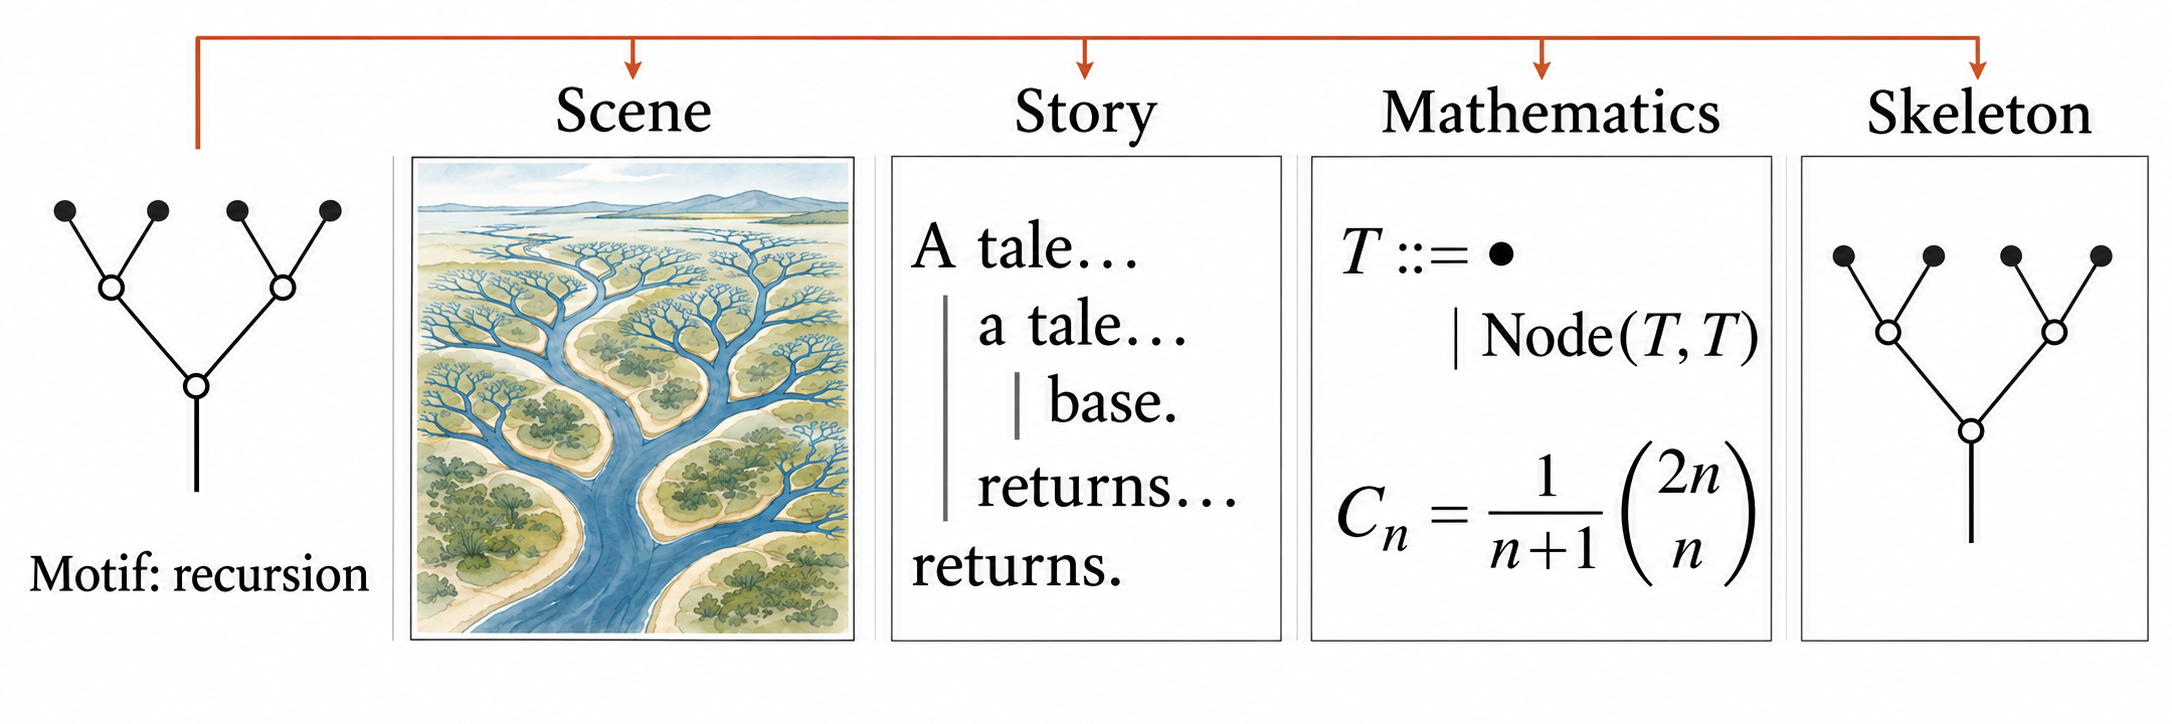
GEB-Bench calls each mode of presentation a voice. A scene realizes a relation through visible composition. A story realizes it through the order, repetition, and arrangement of its telling. A mathematical statement gives an associated formal construction. A programmatic skeleton exposes the intended organization with much of the surface content removed.
The same label ties these voices together, but the ties need careful interpretation. A photograph, a narrative device, and a theorem need not be equivalent definitions of a fully specified mathematical object. They are designed realizations or associations of a recognition target. This is why cross-voice matching is an analogy task rather than a simple conversion between two notations.
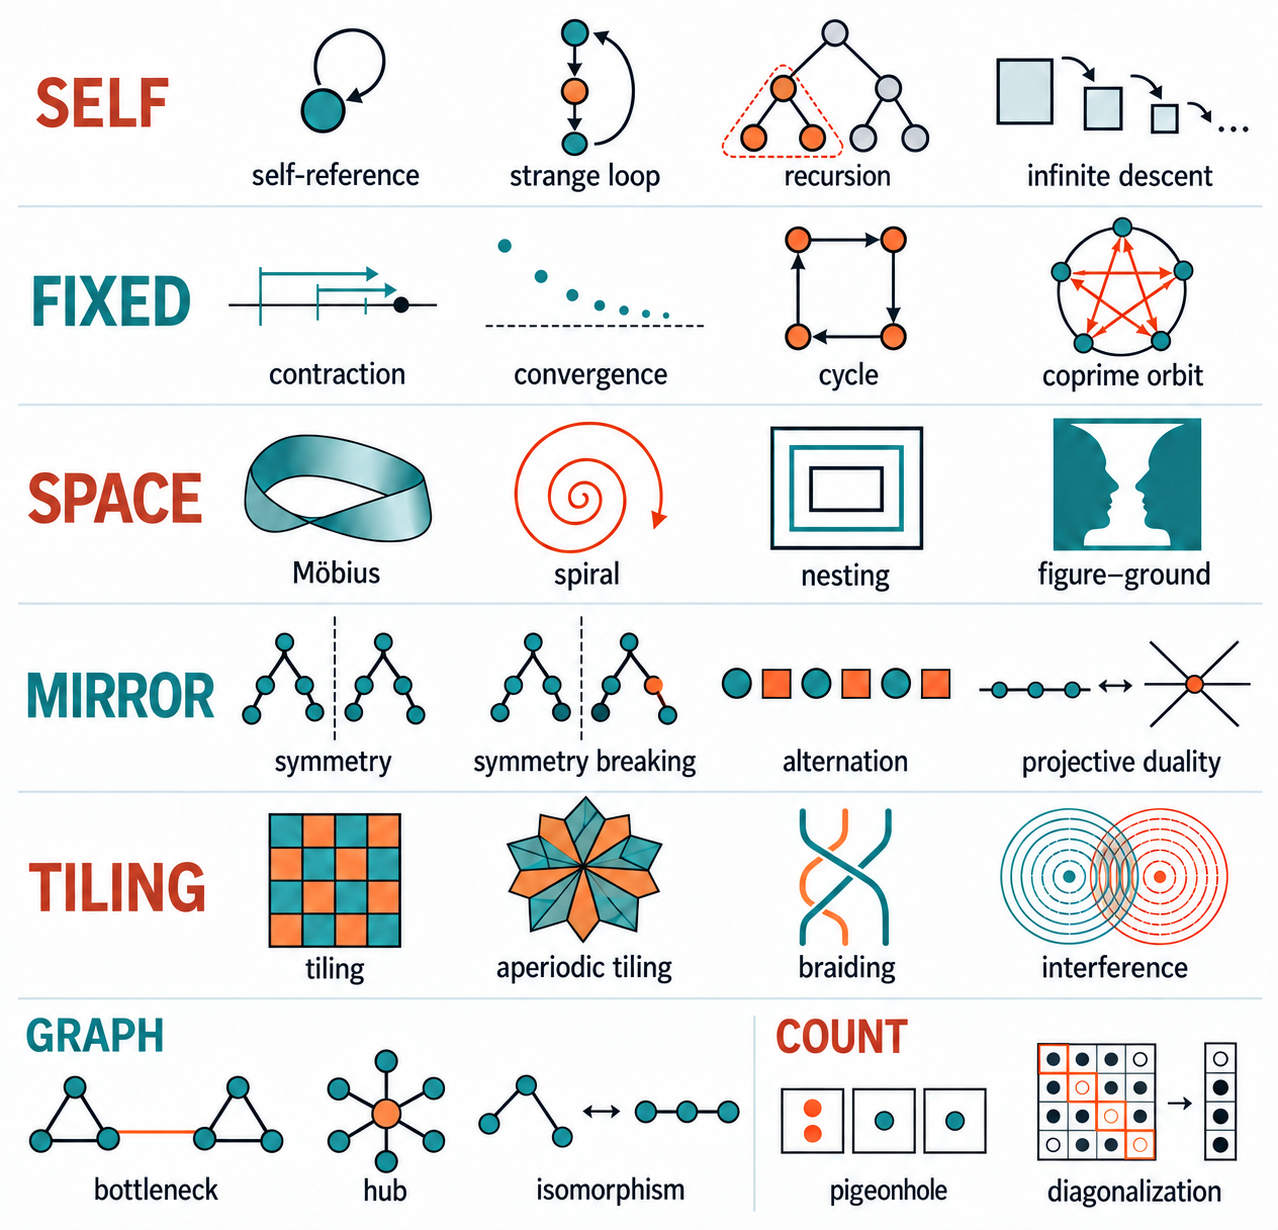
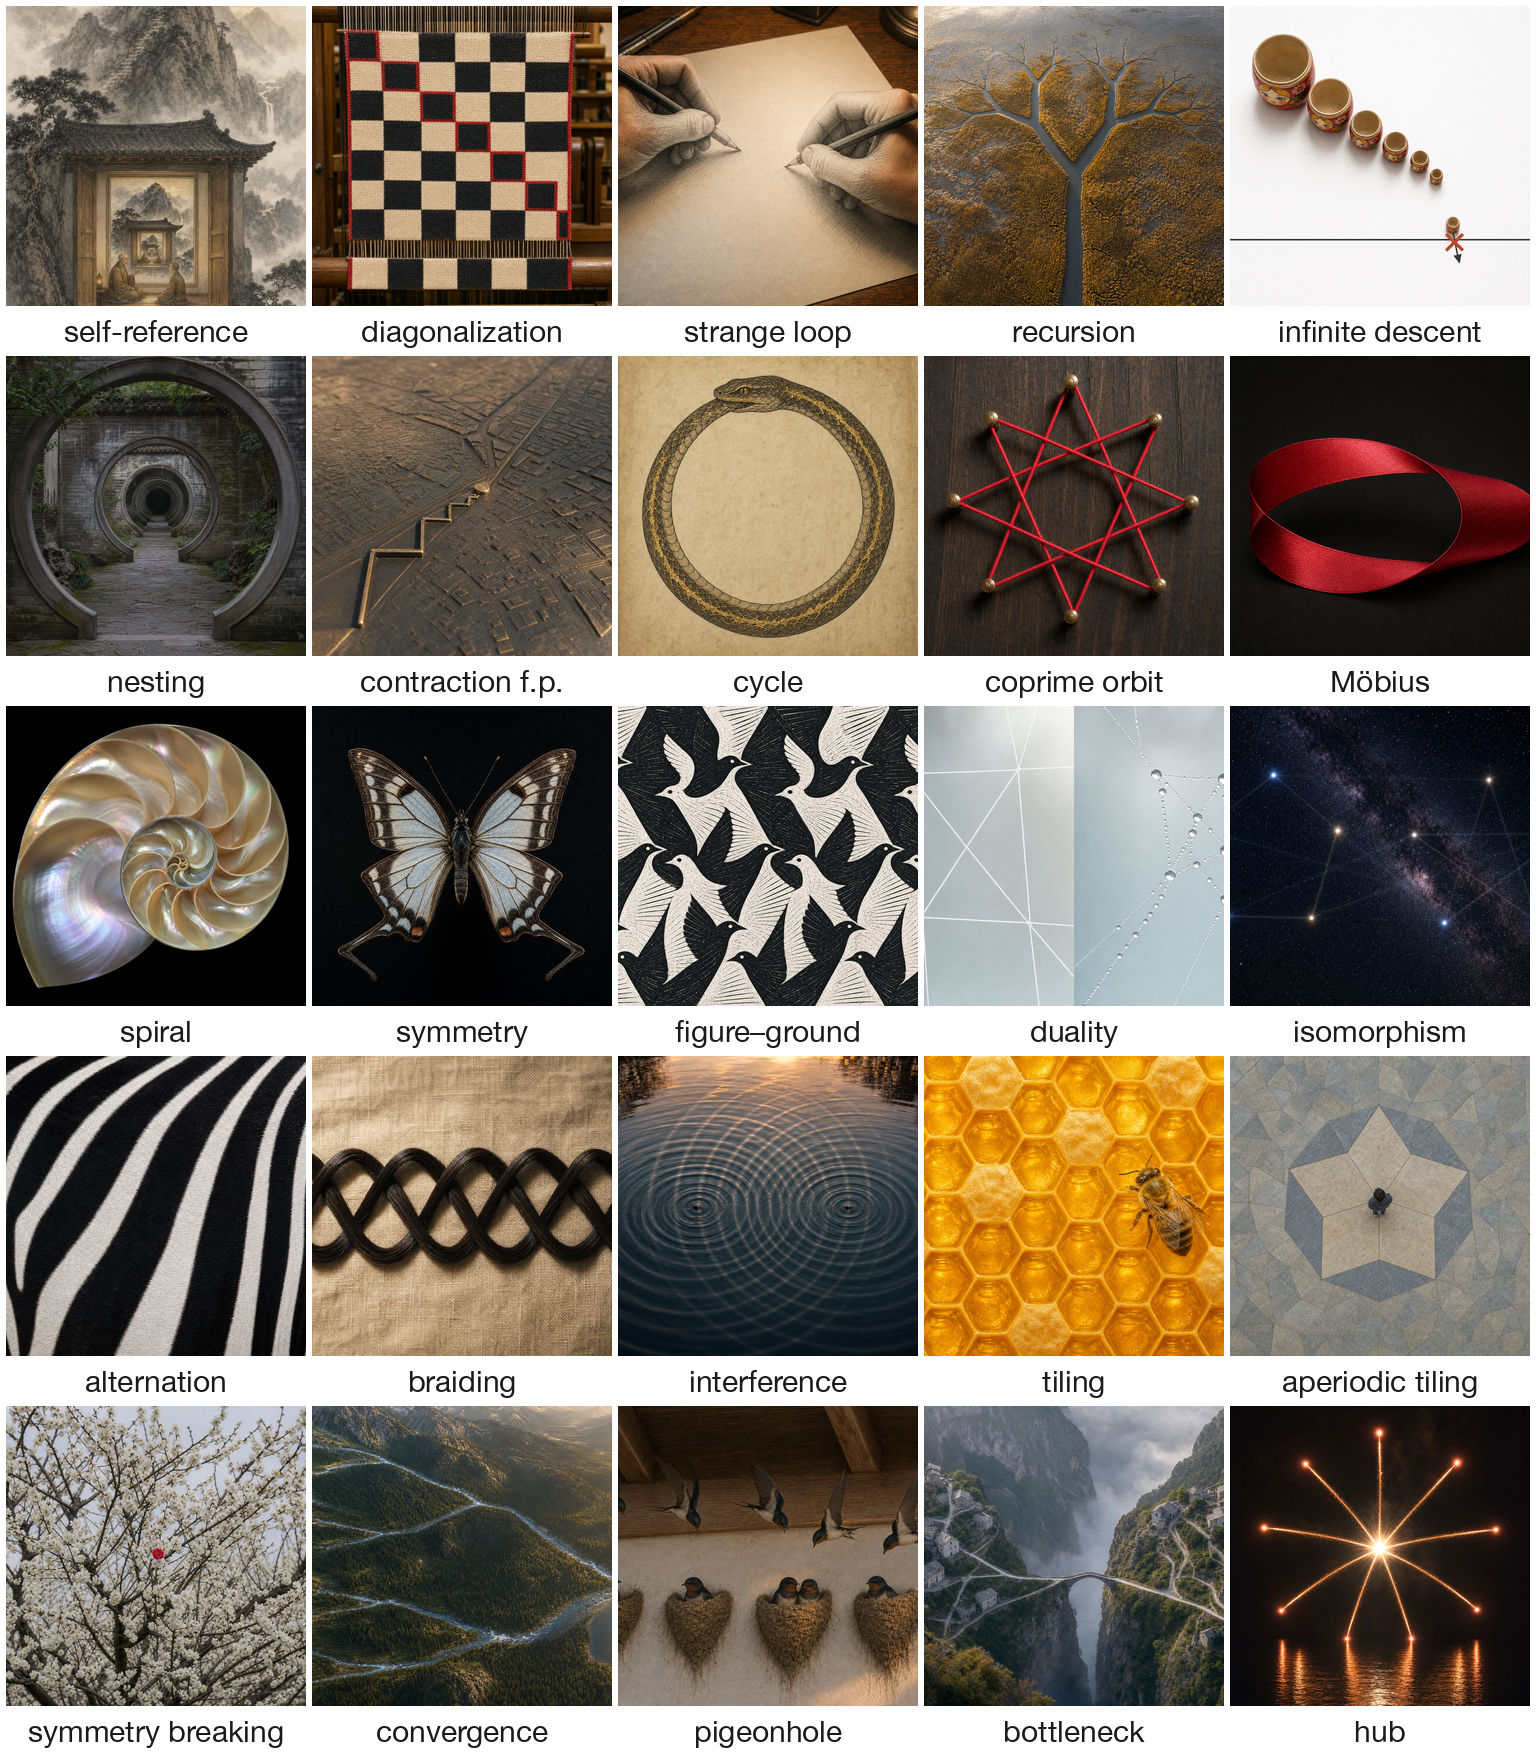
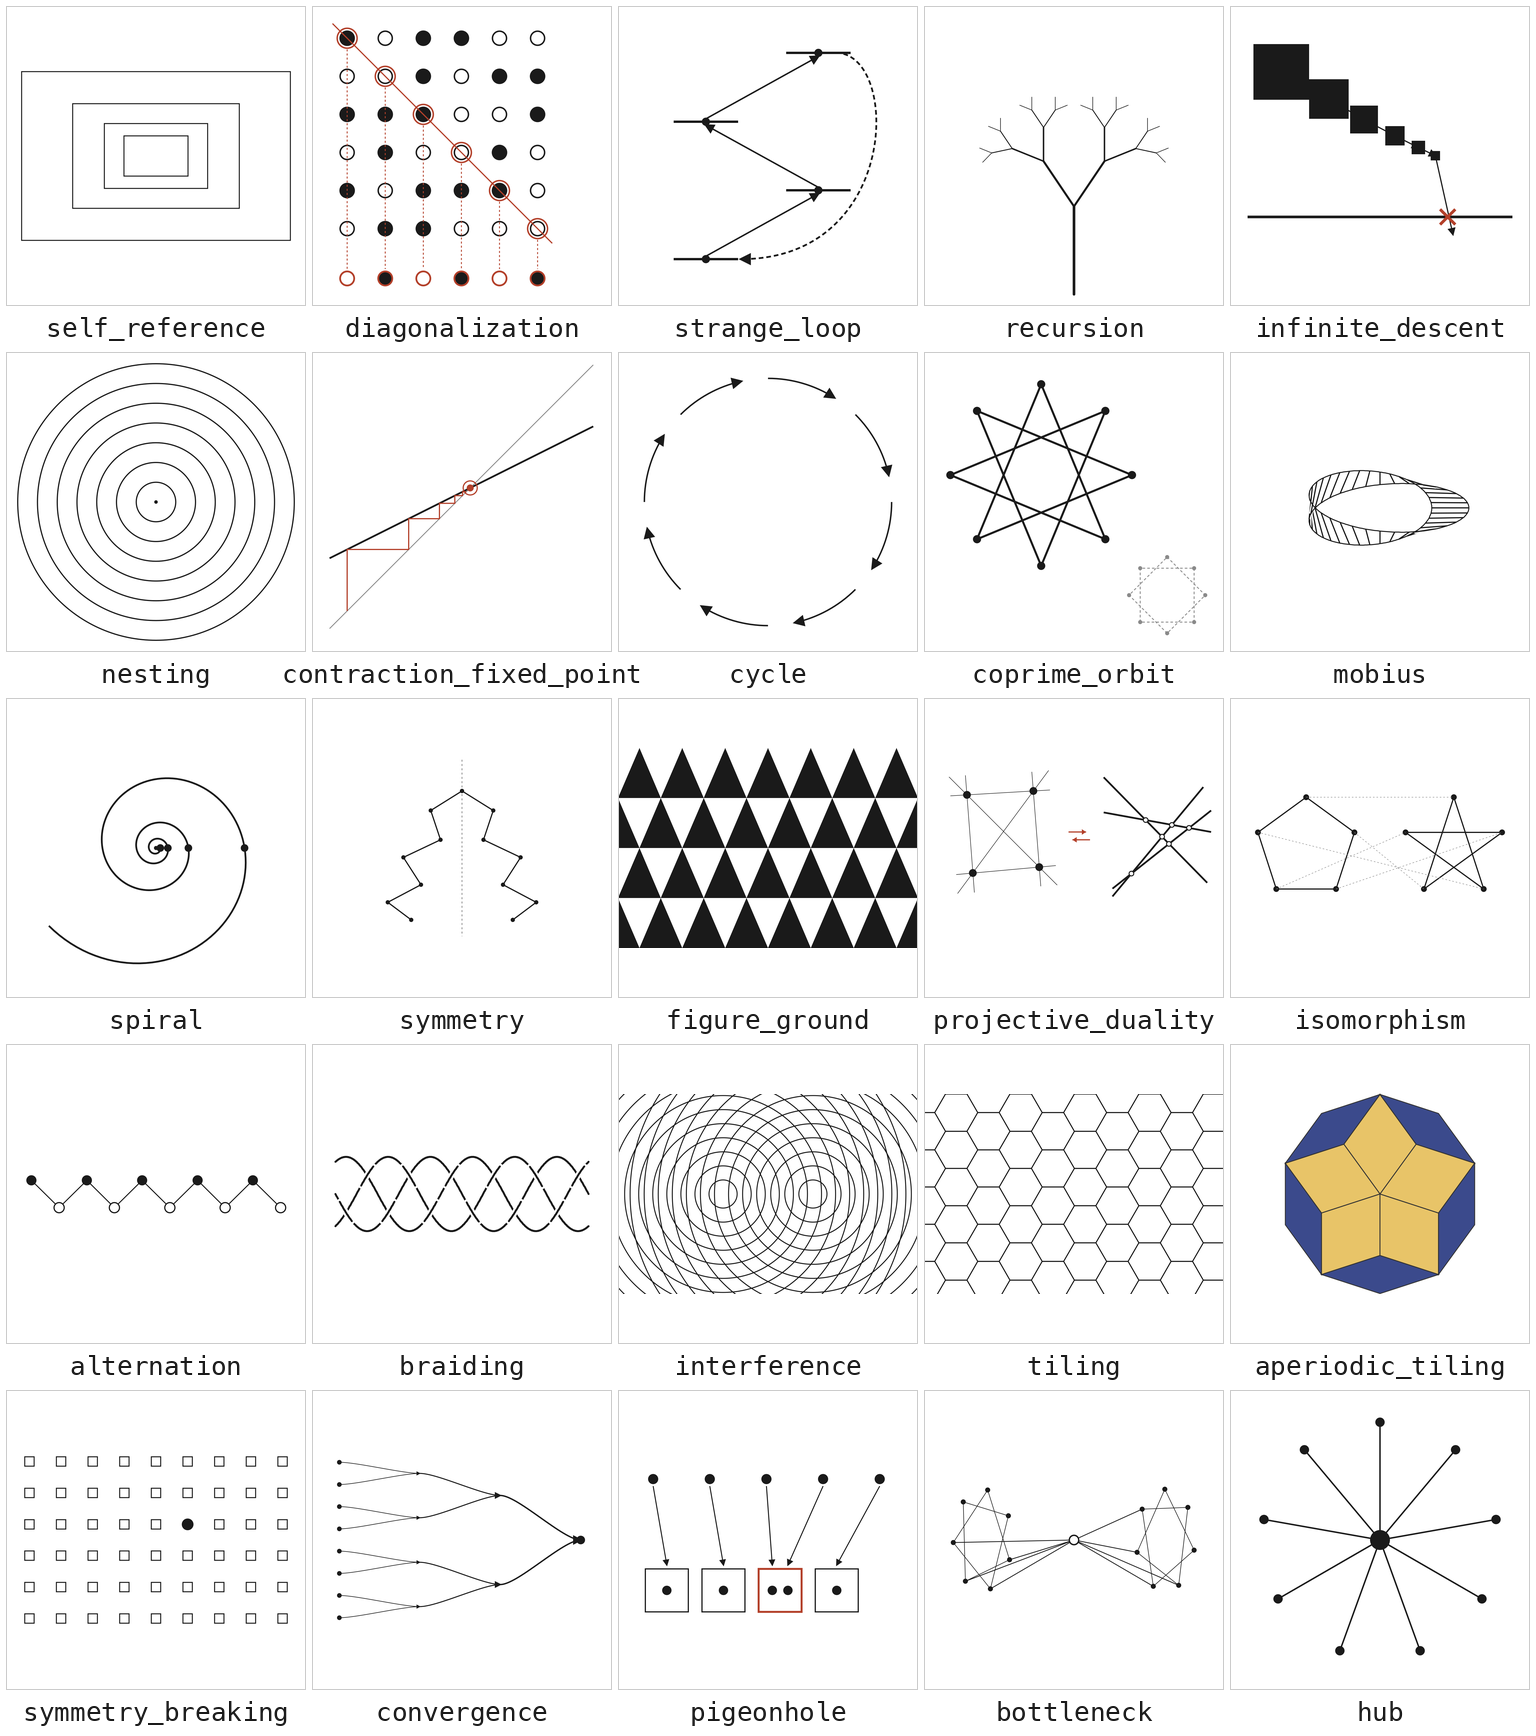
The library fixes 25 motifs and organizes them into seven conceptual reading groups. These groups help a reader navigate the collection; the scored answer remains the individual motif. Neighboring motifs are especially useful because a plausible answer can preserve the topic while losing the relation.
Stories must enact their structure
A story about recursion can simply mention the word recursion. That makes a weak test: a model may recover the label without examining how the story works. The construction pipeline instead uses form devices. Order, recurrence, symmetry, or self-inclusion should appear in the telling itself, and executable checks inspect the relevant sequence and repetition of story units.
Each item links its construction target, concrete realization, and evaluation questions. A story can satisfy an ordering rule while inviting more than one reading; these linked components make it possible to inspect how the answer follows from the item.
For visual items, the construction specifies the intended relation. Aperiodicity concerns the underlying tiling rule, while self-reference requires a scene to refer back to its own representation. Evaluating these items means identifying that relation within the rendered scene.
Recognition and matching ask different questions
Identification presents one item and asks which motif it instantiates. Cross-voice matching presents a source item together with candidates in another voice. The model must choose the candidate that shares the source’s motif. Scene-to-story, scene-to-mathematics, and story-to-mathematics comparisons change what must be carried across the gap.
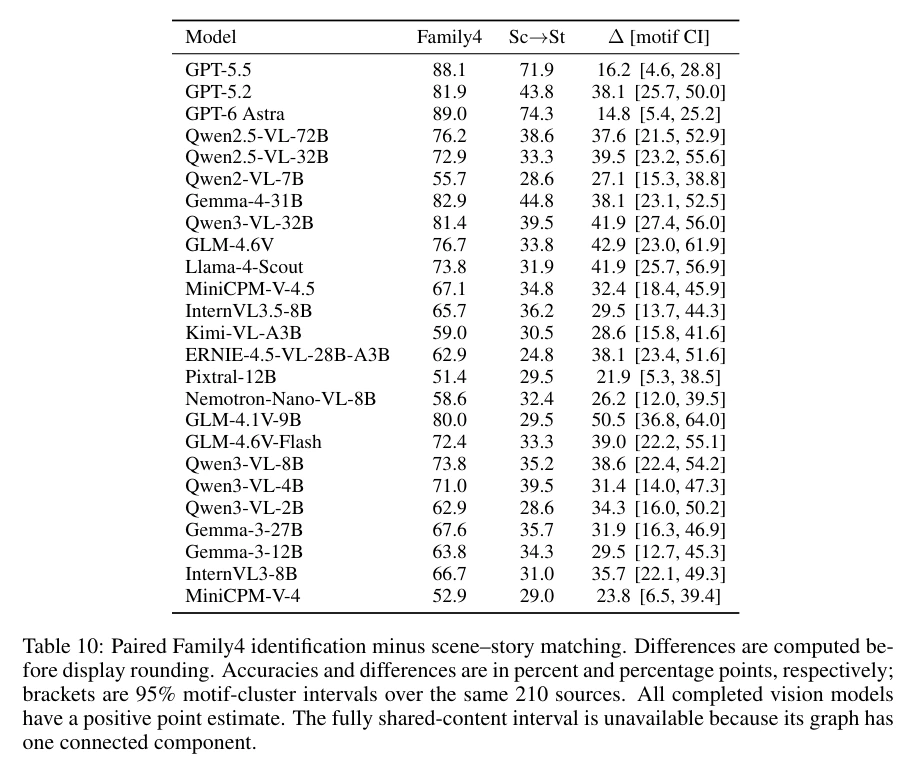
The paired Family4 comparison is especially informative. It holds the source picture and the ordered candidate motif identities fixed. One condition gives motif names and structural descriptions; the other gives four complete stories. Both are four-way choices on the same 210 source scenes. Candidate length, semantic explicitness, and reading requirements still differ, but neither a different image pool nor a different guessing floor explains the paired accuracy gap.
| Model | Family4 | Scene → story | Difference |
|---|---|---|---|
| GPT-5.5 | 88.1% | 71.9% | 16.2 pp |
| GPT-6 Astra | 89.0% | 74.3% | 14.8 pp |
| Qwen2.5-VL-72B | 76.2% | 38.6% | 37.6 pp |
| Qwen3-VL-32B | 81.4% | 39.5% | 41.9 pp |
These entries reproduce the manuscript’s paired compatibility-scoring table. The reported difference is computed from the underlying observations, so a displayed difference may differ slightly from subtracting two rounded percentages. The key result is shared across the completed vision roster: replacing motif descriptions with full stories lowers accuracy.
Why knowing both endpoints still leaves a gap
A particularly revealing error occurs when the model separately identifies the source and every candidate correctly, then selects the wrong cross-voice match. Component recognition has succeeded, yet it does not compose into a reliable correspondence judgment. That makes the benchmark useful beyond a leaderboard: the linked questions distinguish a failure to recognize an endpoint from a failure to connect recognized endpoints.
The paper also compares model sizes and candidate manipulations. Identification improves more consistently than matching across the evaluated Qwen sizes. Withholding the image tests whether the candidates alone supply strong cues. Rotating answer positions tests whether a choice remains stable when content stays fixed. These controls locate dependencies of the administered task; they do not turn a choice accuracy into a general measure of abstract reasoning.
Reply format is another separate axis. Compatibility scoring extracts a valid answer from a longer response, whereas strict scoring requires the requested single JSON object. Both scores use the same retained replies. A gap between them describes answer-format compliance, not an additional attempt or a new reasoning experiment.
A close look at another relation
Interference illustrates why shared content and shared organization can come apart. Two repeating patterns can superpose into a joint pattern. A schematic makes the periodic components easy to see; a scene of ripples places the same intended organization inside surface texture, illumination, and perspective. Matching it to a story requires finding the interaction of patterns in the form of the narrative.
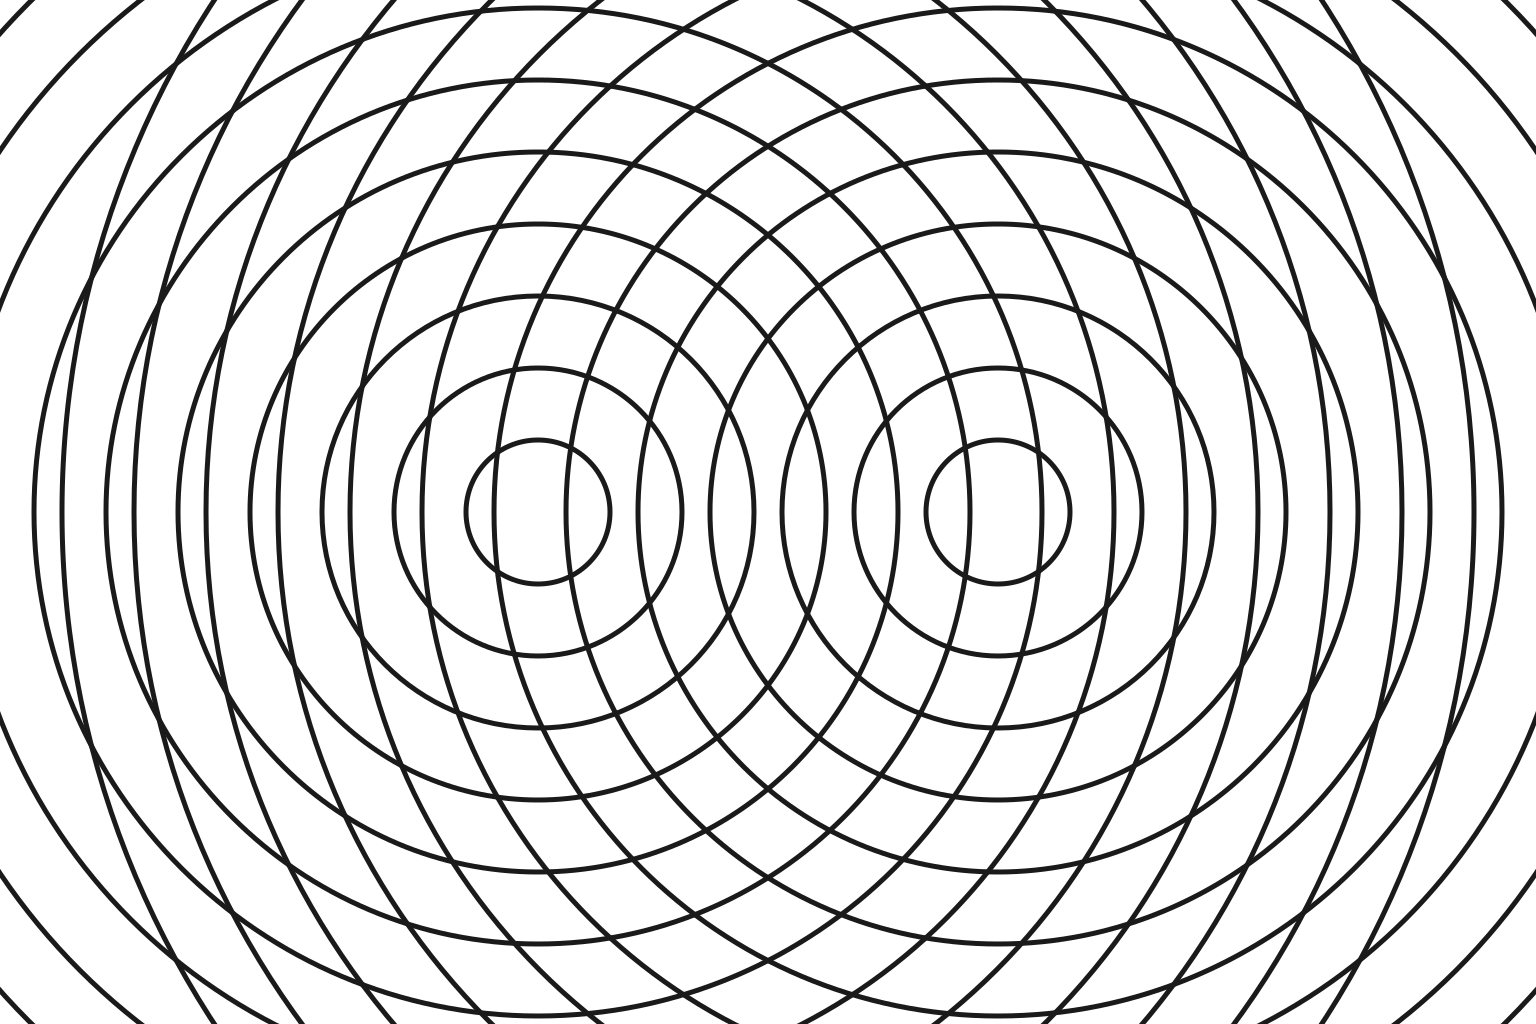
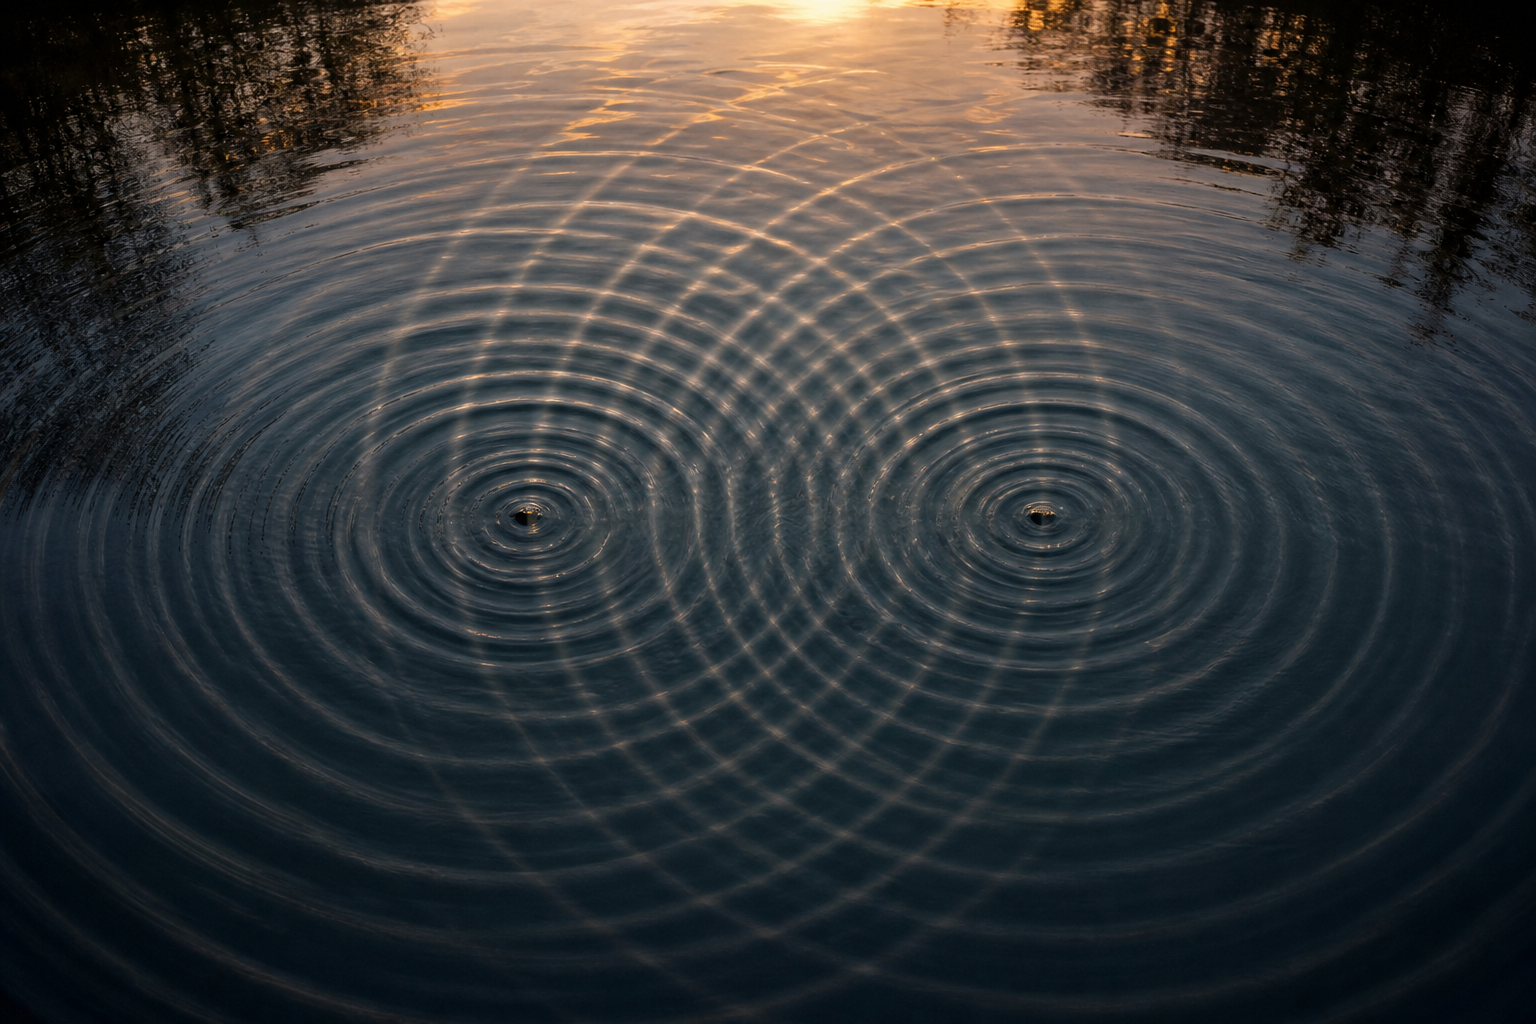
The hard question is therefore relational: which parts correspond, which operations are preserved, and which nearby interpretation would change the answer? A model that relies only on the presence of waves, mirrors, or repeated words can succeed on familiar examples and fail when the same relation arrives with new content.
A categorical perspective on analogy
Category theory offers a useful language for this ambition. One studies objects together with the maps between them, and asks what structure a translation preserves. A functor must preserve identities and composition. Applied as a research perspective here, this shifts attention from naming an isolated pattern toward explaining why different realizations belong together and how a change in one realization should correspond to a change in another.
The scene, story, and mathematical voices turn this perspective into a concrete matching problem. Models can recognize the intended relation at both endpoints and still fail to match it across image and text. Naming the relation and transporting it between modalities are distinct abilities.
This is the scientific opportunity opened by GEB-Bench. Abstraction can be tested through controlled changes of voice, paired component judgments, candidate manipulations, and inspectable examples. The resulting errors identify where a system’s apparent familiarity stops becoming transferable relational knowledge.